A cloud application can look like one thing to its user: a website, a file library, or a business tool. Behind that screen, several systems have to cooperate. A server runs code, storage holds data, and a network carries requests between the user and those resources. If any one of the three is missing, the application cannot do much.
Cloud computing makes those resources available without requiring every organization to buy and operate the underlying equipment. The important change isn’t that servers have disappeared. It’s that a provider runs the physical infrastructure and gives customers a way to request, connect, and release portions of it as needed.
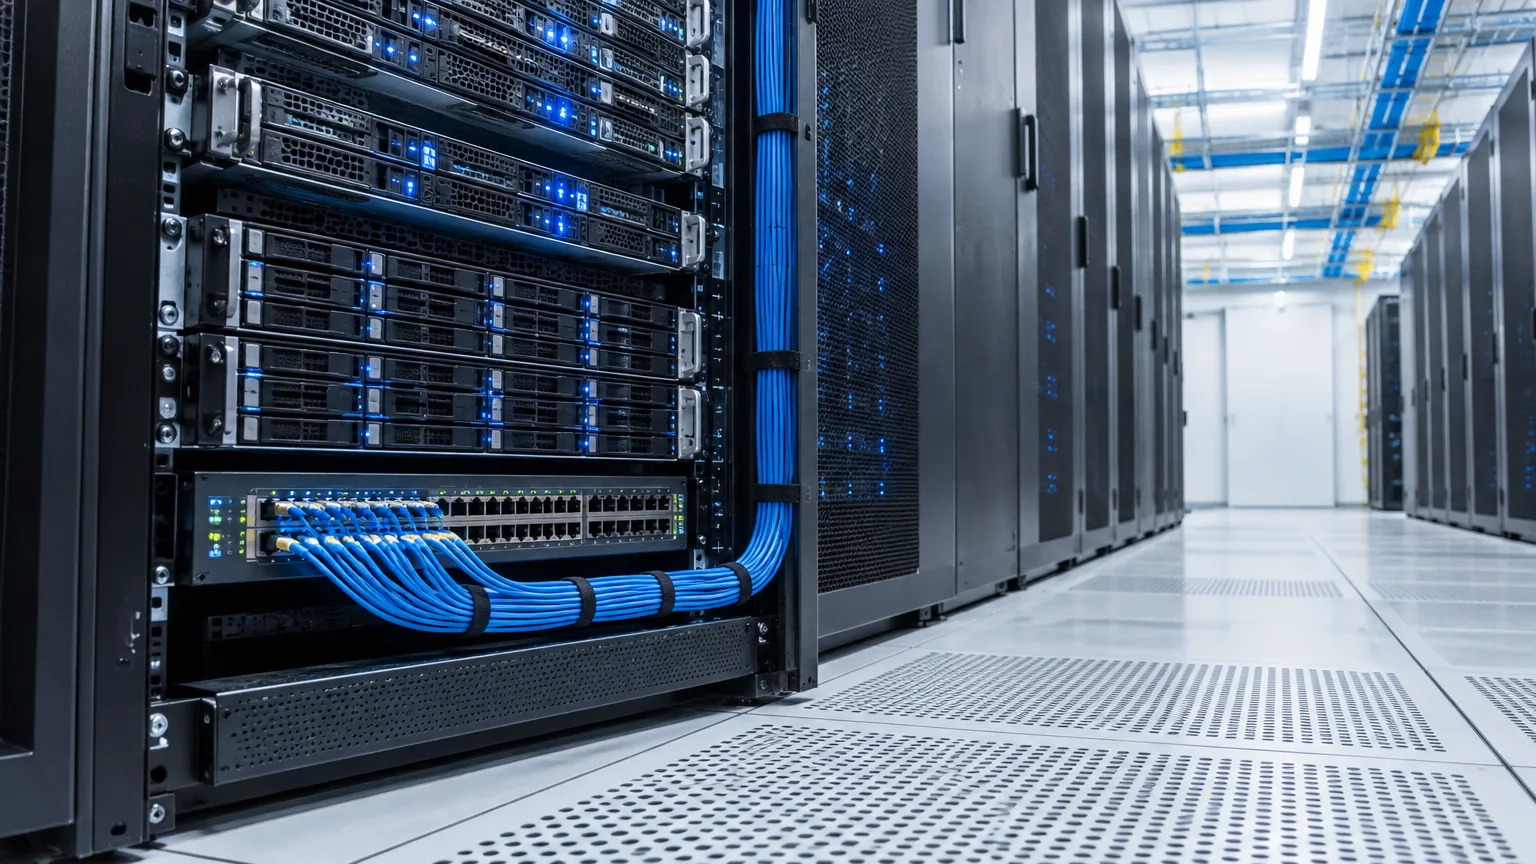
The cloud has a physical layer and a software layer
Cloud providers operate data centers filled with computers, storage devices, and networking equipment. Software above that hardware turns it into resources customers can provision through a console or an application programming interface (API). The National Institute of Standards and Technology’s definition of cloud computing describes a shared pool of resources with on-demand access, rapid provisioning, and measured use.
That software layer is what makes the model different from simply renting a machine in someone else’s building. A customer can request a server, attach storage, place it on a network, and later change or remove those resources without handling the physical hardware. Providers manage the pool; customers decide how to assemble the services they use.
The word shared needs care. Multiple customers may use resources within the same provider infrastructure, but they don’t simply log into one another’s applications or data. The provider supplies isolation mechanisms, while customers still have to configure access to their own resources correctly.
Servers provide the computing power
A cloud server supplies processing power and memory to run an operating system and applications. Often it’s a virtual machine: software presents part of a physical computer as an independent machine. A hypervisor helps allocate hardware resources among those virtual machines. AWS’s Nitro Hypervisor, for example, partitions CPU and memory resources for its virtualized EC2 instances.
A team might put its web application on two virtual machines rather than buy two physical servers. It can choose a machine size, install or deploy its software, and replace the instances when its needs change. Some cloud workloads instead use containers, managed application platforms, or functions. Those options change how much server management the customer sees; they don’t eliminate the need for hardware somewhere underneath. With a service such as AWS Lambda, customers run code without provisioning or managing servers, while the provider handles the underlying compute infrastructure.
Compute is best thought of as the place work happens, not necessarily the place valuable data should live. If an application depends on files kept only on one replaceable server, replacing that server may also disrupt access to those files. Separating compute from persistent storage makes it easier to add, remove, or recover servers.
Storage gives applications somewhere to keep data
Cloud storage isn’t one universal disk. The right form depends on how an application reads and changes its data.
Block storage acts much like an attached drive. An operating system can put a file system on it, and an application can use it for frequently updated data. Amazon EBS volumes are block-storage devices that can be attached to EC2 instances; they can persist beyond the life of a running instance. An EBS volume and the instance using it must be in the same AWS Availability Zone.
Object storage keeps items such as images, documents, and backups as objects accessed through a service interface rather than as sectors of an attached drive. In Amazon S3, an object contains data and metadata and is identified within a bucket by a key, with a version identifier when versioning is enabled. An application can store a customer’s uploaded photo as an object while keeping the customer’s account details in a database.
File storage presents a shared file system. That can suit applications whose servers need to work with the same files and directories. For example, Amazon EFS can provide a file system to multiple EC2 instances.
These choices solve different problems. Object storage is not automatically a substitute for an application’s disk, and an attached volume is not automatically the best place to serve a large collection of uploaded files. For personal files, the related question is how to protect copies over time; our guide to cloud storage and external drives as backup options examines that distinction.
Networks connect the pieces—and control who can reach them
A cloud network gives resources addresses and paths for communicating. Providers also offer software controls for dividing that network into smaller sections, directing traffic, and filtering connections. In AWS, a virtual private cloud, or VPC, can contain subnets with route tables that determine where traffic goes. An internet gateway alone doesn’t expose a server: internet access also depends on routes, addressing, and security rules.
This is why “in the cloud” doesn’t mean “open to the internet.” A public-facing web service may accept requests from users, while an application server or database behind it accepts connections only from specified parts of the cloud network. Keeping those paths deliberate reduces unnecessary exposure and makes failures easier to trace.
Networking also helps distribute work. A load balancer receives traffic and sends it to registered targets, such as application servers. Health checks can keep it from sending new requests to a target that isn’t responding. The load balancer doesn’t perform the application’s work; it helps requests reach a server that can.
What happens when someone opens a cloud-hosted page?
Consider a small online store. Its setup might use a public load balancer, two application servers, a database, and object storage for product images. A request follows a path like this:
- The shopper’s browser sends a request to the store’s web address. The network directs it toward the store’s public entry point.
- The load balancer chooses an available application server. That server runs the code for the requested page.
- The application retrieves product information from its database. If the page needs an image, it can reference an object stored separately.
- The server sends its response back through the network to the shopper’s browser.
The exact route varies by application, but the division of labor stays useful: compute processes the request, storage supplies or retains data, and networking moves traffic while enforcing access boundaries.
This example also shows why a faster server alone may not fix a slow page. The delay could come from a busy database, a large image, a poor network path, or application code that makes too many requests. Cloud infrastructure is a connected system, not three independent purchases.
On-demand capacity still needs planning
Cloud resources can be created and released quickly, which helps when demand changes. If store traffic rises, an organization can add application servers and let a load balancer send requests to them. With an automatic scaling policy, that adjustment can follow a measured signal such as CPU use or requests per server. AWS target-tracking policies, for example, adjust a group’s capacity around a chosen metric and target value.
Scaling is not instantaneous or unlimited. A new server needs time to start and become ready; a database or another shared component may become the bottleneck; and a scaling group operates within configured limits. More servers help only if the application can use them.
Location matters, too. Providers divide infrastructure into geographic regions and smaller deployment areas often called zones. Placing application servers across zones can help an application withstand a zone-level failure, provided its data and networking are designed for that arrangement. Google Cloud’s guidance on regions and zones likewise recommends distributing resources according to availability needs and choosing locations with latency and data-location requirements in mind.
How much does the provider manage?
Cloud services sit at different distances from the hardware. With infrastructure as a service, a customer provisions resources such as virtual machines, storage, and networks, then manages much of what runs on them. A managed platform takes on more of the operating work so developers can focus on deploying an application. Software as a service goes further: customers use an application operated by someone else.
Those categories describe responsibility more than they describe different physical clouds. A business may use virtual machines for one system, a managed database for another, and a subscription software application for email. Each choice changes what its team must configure, maintain, and troubleshoot.
Security follows the same pattern. The provider protects and operates underlying infrastructure, but that doesn’t make every customer setting safe by default. Under AWS’s shared responsibility model, a customer running an EC2 instance manages its guest operating system, application software, and security-group configuration. For more abstracted services, the provider manages more of the stack, while the customer still manages its data and access decisions.
Three assumptions that cause trouble
The first is that cloud capacity is free to leave running because it was easy to create. Metering makes costs flexible, not necessarily small. Compute time, stored data, and outbound data transfer can all affect a bill; S3 pricing also includes factors such as requests and retrievals. A test server or unused storage volume that no one deletes can continue to cost money.
The second is that stored data is automatically a backup. Durable storage helps protect against some equipment failures, but it doesn’t by itself provide a way back from every mistaken change or deletion. Recovery needs to be designed and tested. In S3, for instance, versioning can help recover overwritten or accidentally deleted objects when it has been enabled.
The third is that moving an application to the cloud automatically makes it resilient. An application running on one server in one zone can still have a single point of failure. So can one that has several web servers but relies on a database without a suitable recovery plan. Reliability comes from how the servers, storage, data, and network paths are arranged—not from the word cloud on the invoice.
That is the useful way to picture cloud computing: physical infrastructure operated by a provider, divided into services that customers assemble. Its advantage is the ability to obtain and change those services on demand. Making them work well together remains an engineering decision.